Can a decisions API pick the right model for an agent task? Part 1
Results: 24 synthetic tasks, one run per method. Watch the 80-second walkthrough on YouTube.
When a planner breaks work into tasks, each task still needs an executor: which provider, which model, and how much reasoning. Overprovision every task and you burn budget; underprovision and you pay in rework. In our Workbench, a planner makes that call today using a written policy: classify the work, pick a tier and reasoning level, and only choose lanes that are approved and have capacity.
That choice is a good target for automation: it happens many times a day, the options are bounded, and the policy that constrains it already lives in code. Here's where it sits:
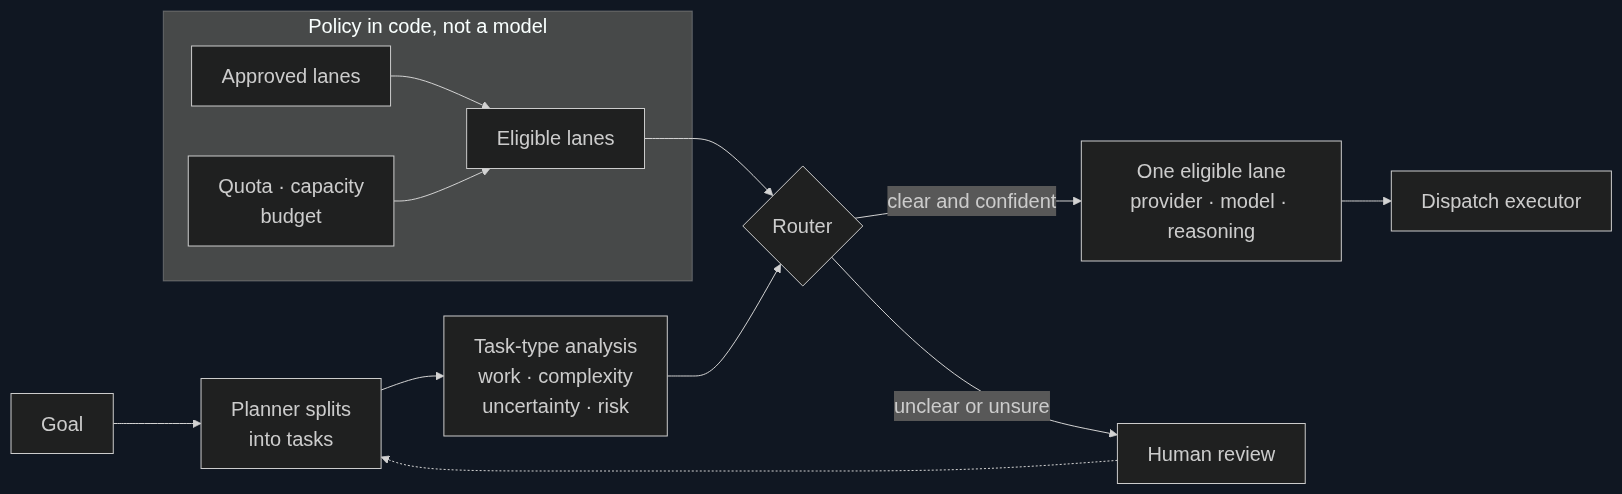
Typed decisions APIs promise a cheaper, faster way to make exactly this kind of bounded choice. Instead of generating text, Google's Gemini Decisions API returns probabilities over options you define. So we asked: does it beat how we already route work?
The setup
Every method saw the same 24 fresh synthetic planning tasks and the same eligible lanes. Code removed unapproved providers and lanes without capacity or budget before any model saw the task, so no method could recommend something it was not allowed to use.
We compared:
- Current practice: our normal Workbench planner role, run blind to the answer key, with its first decision recorded and locked before anything else ran.
- Typed decisions: Gemini Decision 1.
- Ordinary LLMs with a JSON schema: Claude Haiku and Sonnet, and GPT-6 Luna at two reasoning levels through Codex.
- A free model: a 1.7B model on OpenRouter's free tier.
A separate model session labelled the acceptable answers and sealed them before any comparator ran. We locked every method's outputs before unsealing the labels.
What happened
The current planner was right on 23 of 24 cases. Nothing beat it.
| Method | Correct / 24 | Wrong lane | Unneeded review |
|---|---|---|---|
| Current Workbench planner | 23 | 0 | 1 |
| Claude Sonnet / medium | 22 | 2 | 0 |
| GPT-6 Luna (low or medium) | 20 | 3 | 1 |
| Gemini Decision 1 | 17 | 0 | 7 |
| Claude Haiku / low | 15 | 2 | 7 |
Gemini never picked a wrong lane. It also sent seven perfectly routable tasks to a human because its top choice fell below our 0.80 confidence threshold. In this setup its value was safe abstention, not better routing. Sonnet came closest and was about 4% cheaper on the tasks both routed correctly, but it introduced two wrong lanes. The free model hit a provider error after eight tasks, so its result is inconclusive.
How much to trust this
Not much yet, and here's why. The labeler and the baseline planner were separate sessions of the same model family, which probably flatters the baseline. Labels were agent-generated and not yet reviewed by a person. Twenty-four synthetic tasks, one run each, and no downstream execution means no cost-savings claim. We did not test OpenAI's Decisions API or TypeSafe's Jev: neither had a zero-spend path for us.
What's next
This is part 1 of a series. If it's useful to you, Part 2 will pay for the arms we skipped (OpenAI Decisions and Jev), add a labeler from a different model family, and tune the abstention threshold on development data rather than guessing it.
Code, fixtures, the architecture, results and the scoring tool are in the public repository. Tell us what you'd want tested next.
If you'd like to help fund Part 2's paid model runs, you can buy us a coffee.